简介:llama.cpp 是一个轻量级的开源项目,旨在高效地运行基于 Meta 开发的 LLaMA(Large Language Model Meta AI)模型的推理。它以 C++ 编写,优化了模型的性能和资源使用,特别适用于内存有限的设备,比如笔记本电脑或移动设备。除了llama模型,目前llama.cpp也支持其他类型的LLM模型。本文以Qwen2 模型为例,介绍如何在RDK平台部署Qwen2模型。
支持平台:RDK 全系列产品
安装与编译
参考:llama.cpp/docs/build.md at master · ggml-org/llama.cpp · GitHub
git clone https://github.com/ggml-org/llama.cppcd llama.cpp# 编译cmake -B buildcmake --build build --config Release
模型下载
访问ModelScape社区(以Qwen2-0.5B为例) https://modelscope.cn/models/Qwen/Qwen2-0.5B-Instruct-GGUF/summary
1. 搜索找到对应模型(GGUF格式模型)
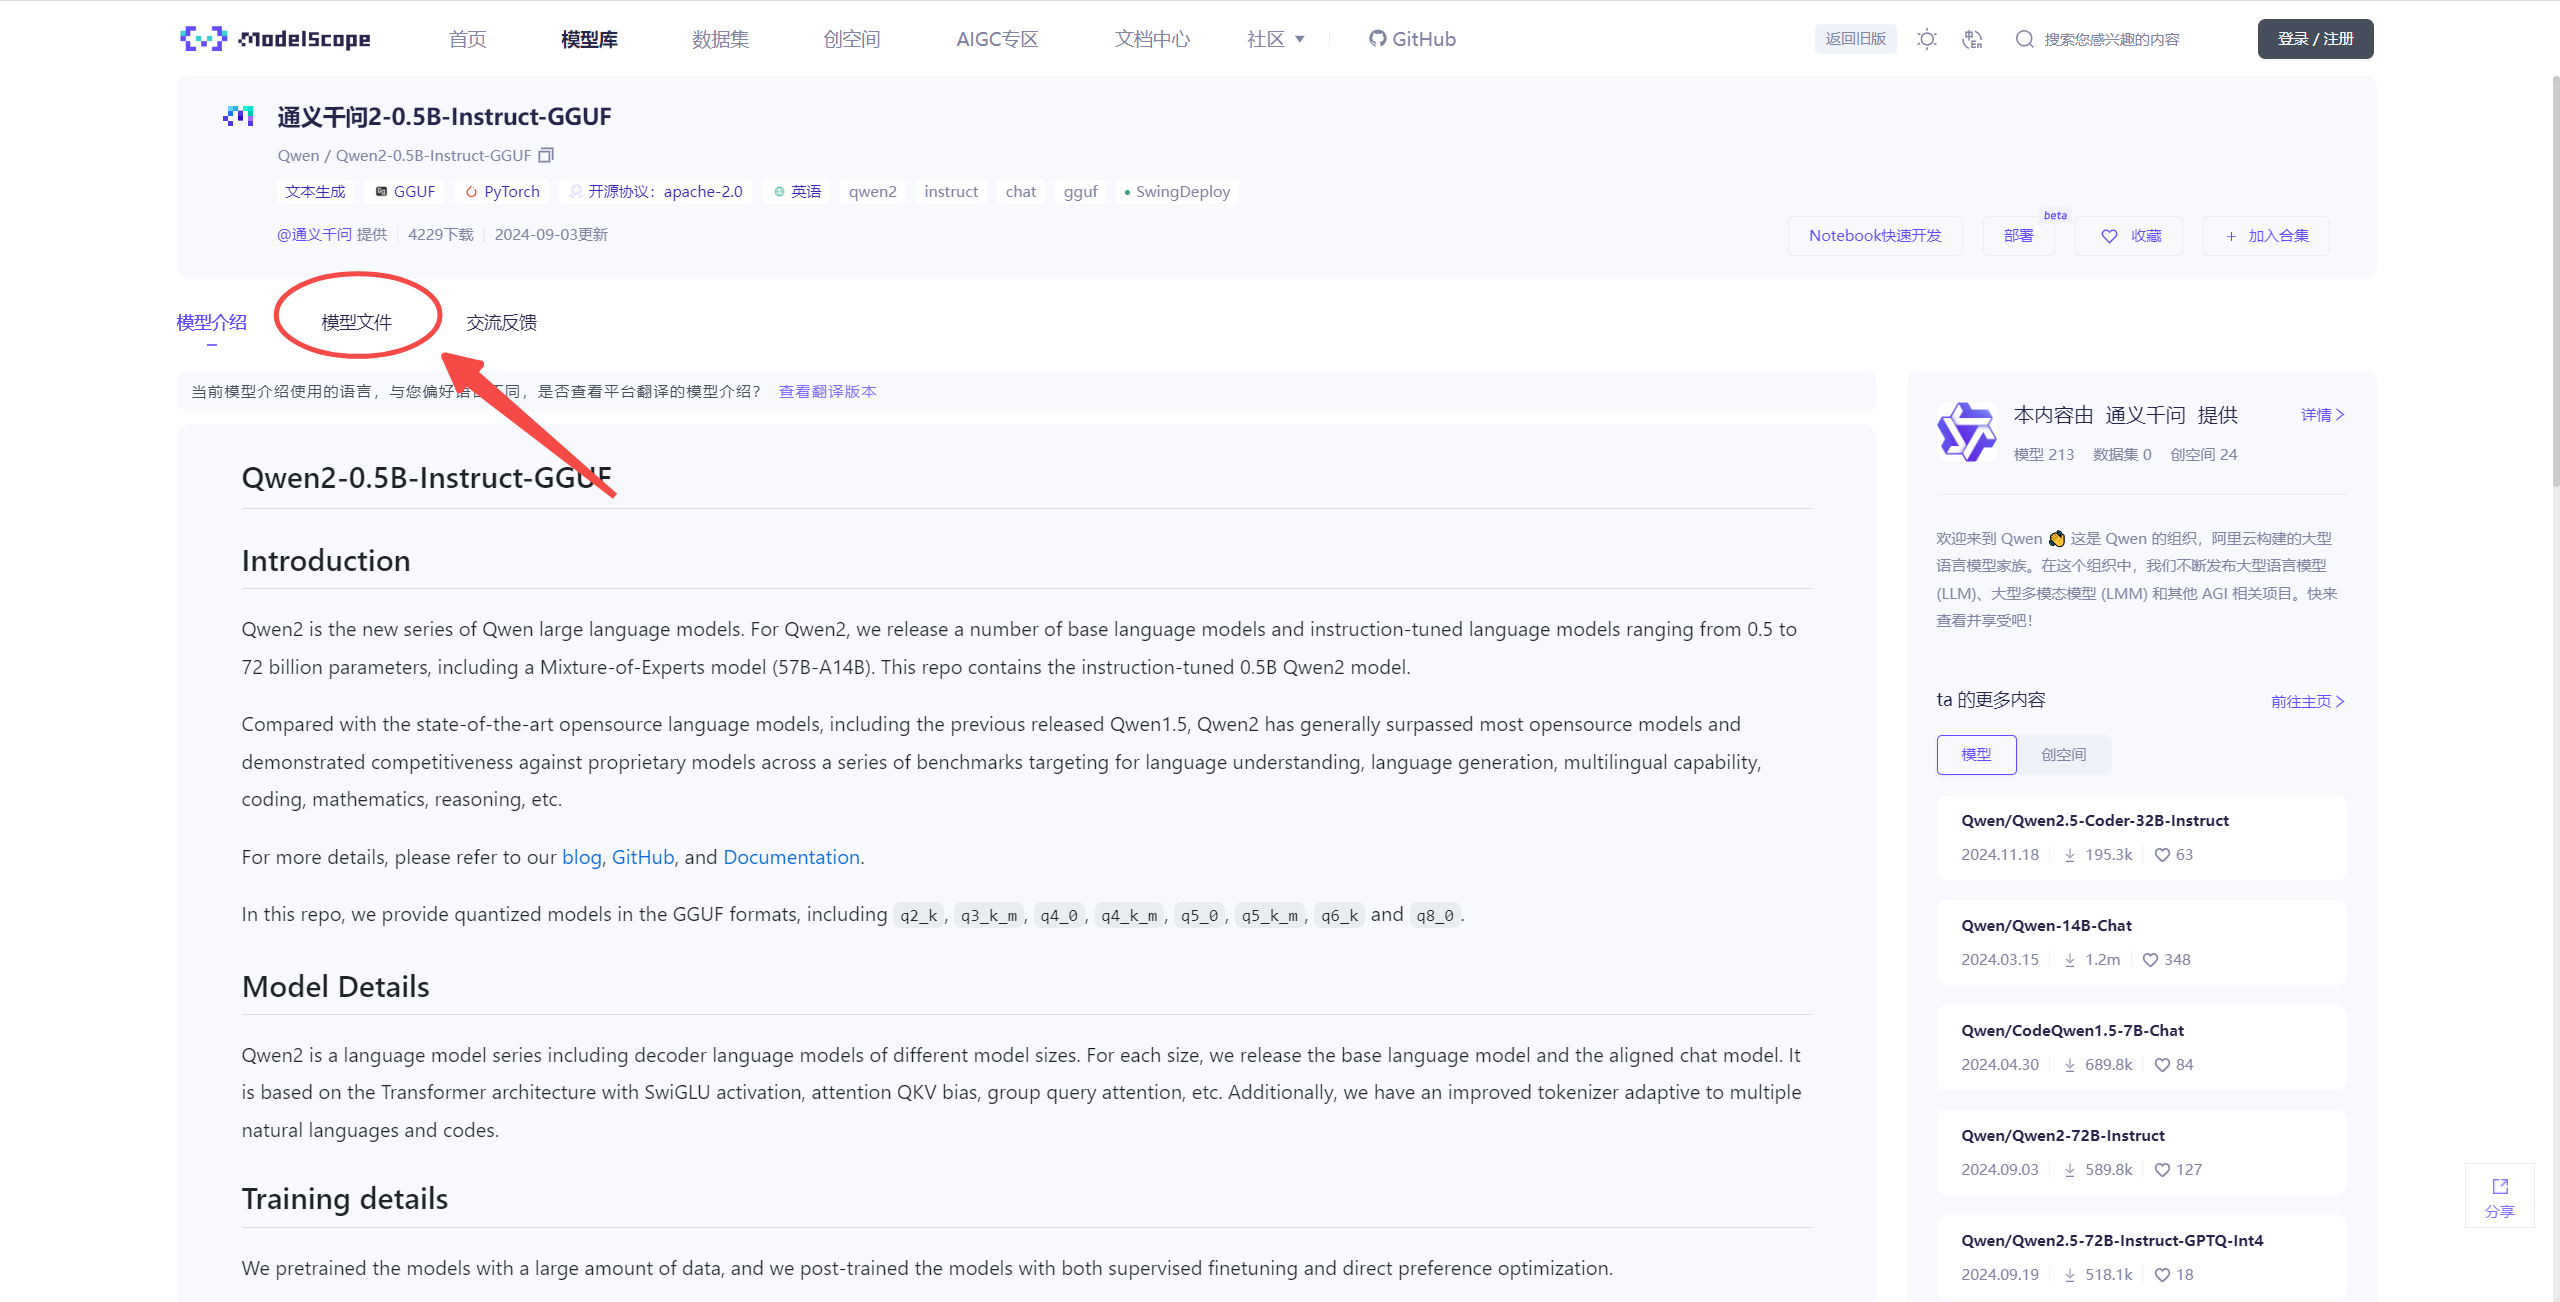
2. 在模型文件栏中下载对应模型,这里以qwen2-0_5b-instruct-q8_0.gguf为例。
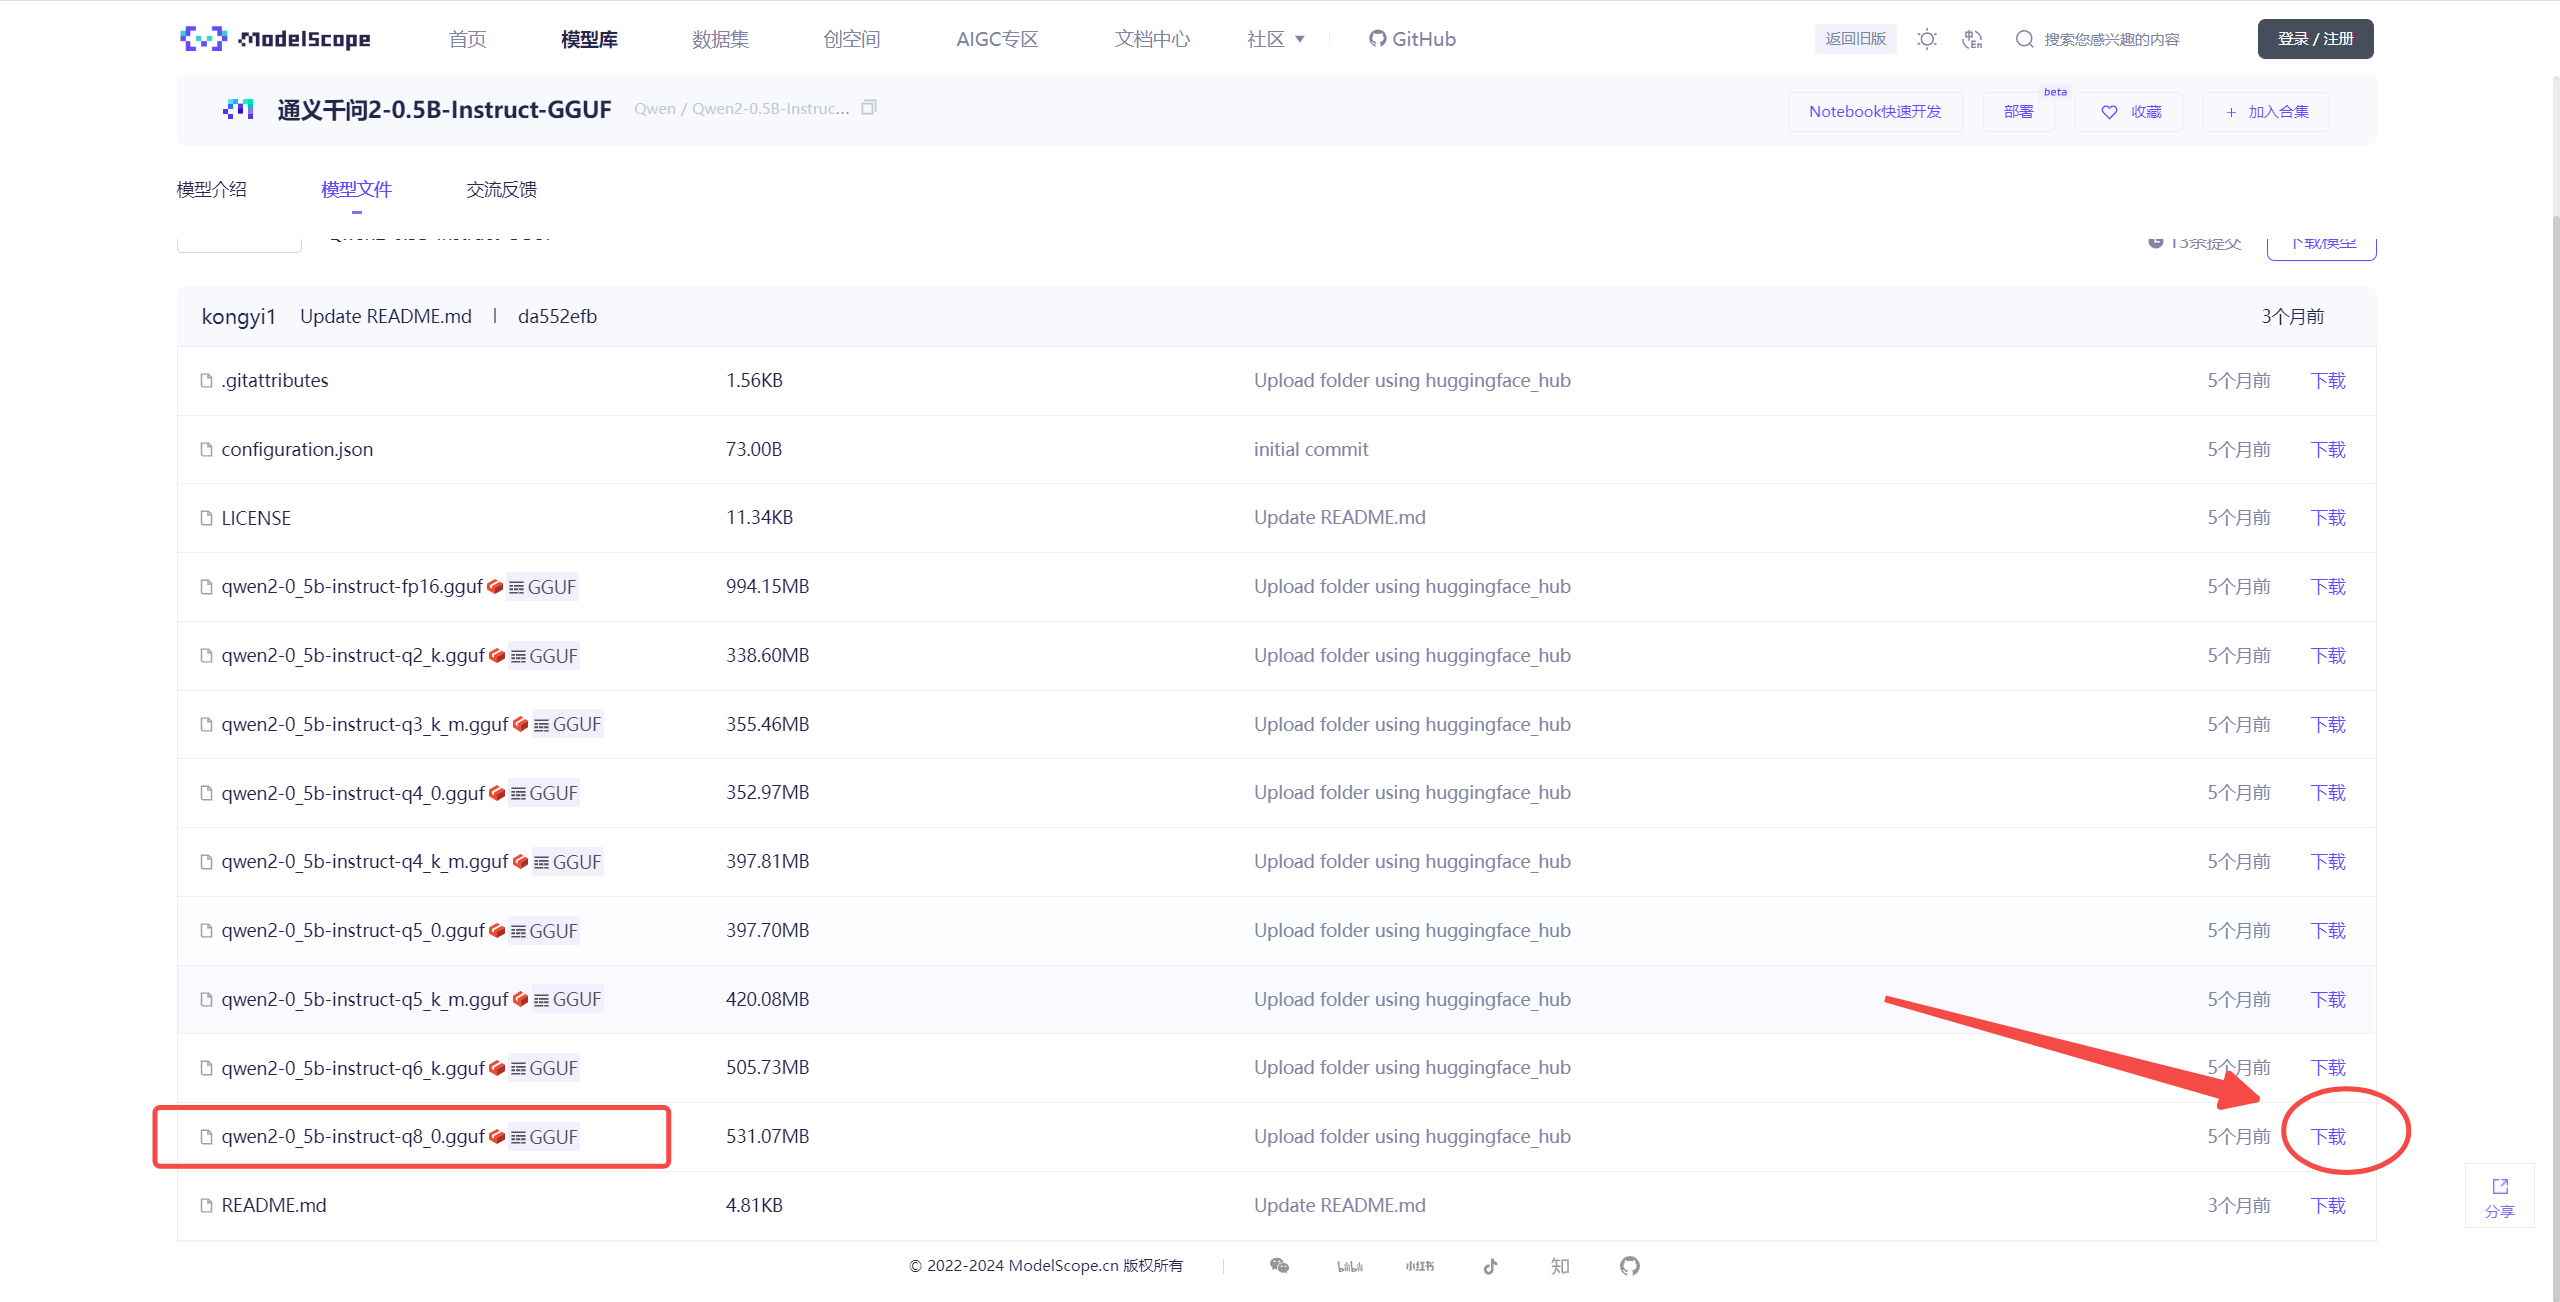
下载后将模型放在板子上。
可通过右键复制下载的链接,直接下载模型到板子上。
wget https://modelscope.cn/models/Qwen/Qwen2-0.5B-Instruct-GGUF/resolve/master/qwen2-0_5b-instruct-q8_0.gguf
板端运行
# 设置CPU频率为性能模式echo performance >/sys/devices/system/cpu/cpu0/cpufreq/scaling_governor echo performance >/sys/devices/system/cpu/cpu1/cpufreq/scaling_governor echo performance >/sys/devices/system/cpu/cpu2/cpufreq/scaling_governor echo performance >/sys/devices/system/cpu/cpu3/cpufreq/scaling_governor echo performance >/sys/devices/system/cpu/cpu4/cpufreq/scaling_governor echo performance >/sys/devices/system/cpu/cpu5/cpufreq/scaling_governor echo performance >/sys/devices/system/cpu/cpu6/cpufreq/scaling_governor echo performance >/sys/devices/system/cpu/cpu7/cpufreq/scaling_governor
运行模型
./build/bin/llama-cli -m qwen2-0_5b-instruct-q8_0.gguf -n 512 -co -i -if -f ./prompts/chat-with-qwen.txt --threads 4
运行结果:
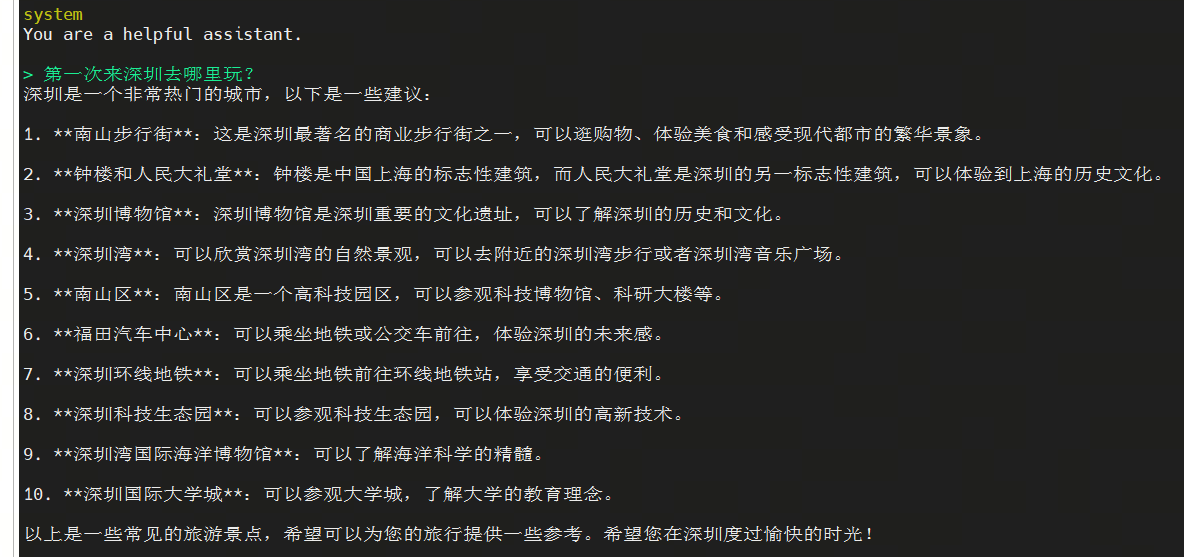
性能结果:可以看到该模型在RDK X5 平台上运行效率为 14.6 tokens/s。
